Chapter 30
The Selectability Score
A brand needs one number that says how likely it is to be selected, and one list that says what to fix first.
Everything else is detail beneath those two. This chapter sets out the score in full. It's the method behind RocMode's scoring, and I've written it so you could build your own.
Be clear about what the number is. It's an index of your odds at the moments that matter, not a count of sales. Nothing yet ties it to market share or revenue. That test is still to come, and this chapter says how it'll be run. The appendix turns it into a worksheet you can fill in by hand.
The unit is the moment
The score is built from the map in Chapter 6. Each moment is one kind of buyer at one step of their journey. Only moments that exist for your brand are scored. A moment you haven't defined is left out, never counted as zero.
Each moment is heard through several buyer questions: the different ways that buyer might ask at that step. Five kinds of buyer and seven journey steps make 35 moments. Three questions for each makes 105 questions, and still 35 moments. More questions make each reading steadier without adding moments.
Six checks in every moment
Each check asks one question, and each uses the tool from its stage chapter.
| Stage | The question | How it can be measured | The tool |
|---|---|---|---|
| Known | Does the buyer, or the machine, already know you? | Two signals: whether AI assistants recognise you by name and tie you to the moment, and your share of search against named rivals | The moment memory map (Ch 13) |
| Found | Do you appear when they ask without naming you? | The share of answers to unbranded questions that name you | The presence sample (Ch 14) |
| Answered | Does what you publish answer what this buyer needs to know? | The share of their questions and objections your site answers | The question chain map (Ch 15) |
| Believed | Is what is said about you accurate, and backed by others? | Accuracy, outside support and consistency, in the answers that name you | The claim, proof and source inventory (Ch 16) |
| Preferred | When you appear, are you the one recommended, with a reason? | How strongly you are recommended, and whether your reason is the one given | The reason gap sheet (Ch 17) |
| Bought | Does the place they land make it easy to say yes? | Whether the page repeats the reason, shows proof and gives a clear next step. Your own sales data, where you have it | The risk-removal ladder and the decision friction audit (Ch 18) |
The seventh stage, Kept, is scored differently. It comes after the formula.
The formula
Known and Found are gates. If a buyer has never heard of you and can't find you, nothing else you do is seen. The other four stages are the quality of what they find.
Gate     = square root of (Known × Found)
Quality  = weighted average of Answered, Believed, Preferred and Bought
Moment   = Gate × Quality
Score    = weighted average of every moment, from 0 to 100
Work each check as a share from 0 to 1, and multiply by 100 at the end.
The multiplication is the point. A brand with perfect answers that nobody finds scores zero, because a gate of zero multiplies everything down to nothing.
The square root softens the gate. Take a brand with Known and quality both at 100, so only Found varies. Named in half the answers in every moment, it scores √(100 × 50) = about 71 in each, and about 71 overall. Now name it in every answer in half its moments, and in none of the rest. It scores 100 in half and 0 in the others: 50 overall.
So the score favours breadth. Being on more lists some of the time beats owning half of them. That matches the evidence on breadth in Chapter 13: brands linked to more buying situations win more buyers and keep more of them.
It's "seen isn't selected" written as arithmetic. Being seen is the gate, and it's worth nothing until it's multiplied by quality: the answers, the proof, the reason and the way to buy.
The weights
Two sets of weights turn the formula into a number. The first is between the four quality stages, and it depends on how your buyers buy. These are the starting weights for the five buying modes (Chapter 7).
| Mode | Answered | Believed | Preferred | Bought |
|---|---|---|---|---|
| Habitual | 10% | 20% | 15% | 55% |
| Quick choice | 15% | 25% | 15% | 45% |
| Considered personal | 25% | 30% | 30% | 15% |
| Owner-led business | 20% | 35% | 30% | 15% |
| Committee | 25% | 30% | 30% | 15% |
In habitual and quick-choice buying, Known and Found already sit in the gate, so inside the quality score Bought carries them, and a hurried choice leaves no room to weigh reasons. In the other three modes the buyer stops to think. Answered, Believed and Preferred decide it.
The second set of weights is between moments. Moments nearer the decision count for more, and your main buyers count for more than occasional ones.
I should be plain about these numbers. They're judgement, not yet fitted to sales data. They're published, versioned and open to challenge. These are version 1.0.
How the weights will be tested
A score nobody has checked against sales is a hypothesis. Here's how I mean to check it.
Score the same brands every quarter, moment by moment, and set each score beside that brand's share of new customers or sales, in the same category and period. If the score has value, brands that score higher should tend to hold more share, and a rise in the score should come before a rise in share, not after it.
If it doesn't, the weights are wrong, and possibly the formula too. Every change gets a new version number and resets the baseline.
This needs data no single firm holds. If you'll share your scores beside your sales or share, I'd like to hear from you at rocmode.com/research. RocMode will also run this test on its own customers' scores, and the findings will be published, whatever they show.
Kept is a moment
A first-time buyer can't have been kept. So Kept isn't a seventh weight.
It's the same six checks asked at a different moment: renew or switch. "Is it worth renewing?" Those moments sit on the same map and are scored the same way. If you hold your own renewal or repeat-purchase data, that's the truth, and the score explains it.
Four kinds of moment
Two of the measures sort every moment into one of four kinds.
| The machine picks you | The machine does not | |
|---|---|---|
| Your site answers the buyer | Won | Hidden |
| Your site does not | Borrowed | Empty |
Hidden is the common one: you have the answer and nobody is sent to it. Borrowed is the fragile one: you're recommended on the strength of what others wrote.
The verdict
| Score | What it means |
|---|---|
| 0 to 24 | Rarely selected |
| 25 to 49 | Sometimes selected |
| 50 to 74 | Often selected |
| 75 and over | Usually selected |
The rules that keep it honest
These matter more than the formula. They're what stop the score becoming the next visibility number.
- Questions that name your brand don't count toward Found. Appearing when you were asked for proves nothing.
- Every score carries a range. AI answers vary from one asking to the next, so one number alone would claim a certainty nobody has.
- Small samples are pulled toward your average, so three lucky answers can't make a moment look won.
- A stage that wasn't measured is shown as not measured and left out. It's never guessed.
- A change to the formula or the questions resets the baseline. A change of method is never reported as progress.
- Only measured outcomes move the score. Publishing a page, finishing a task or switching on a tool does nothing by itself.
That last rule is the one I'd fight for. A score that rises because you used the vendor's product is an advertisement.
One list
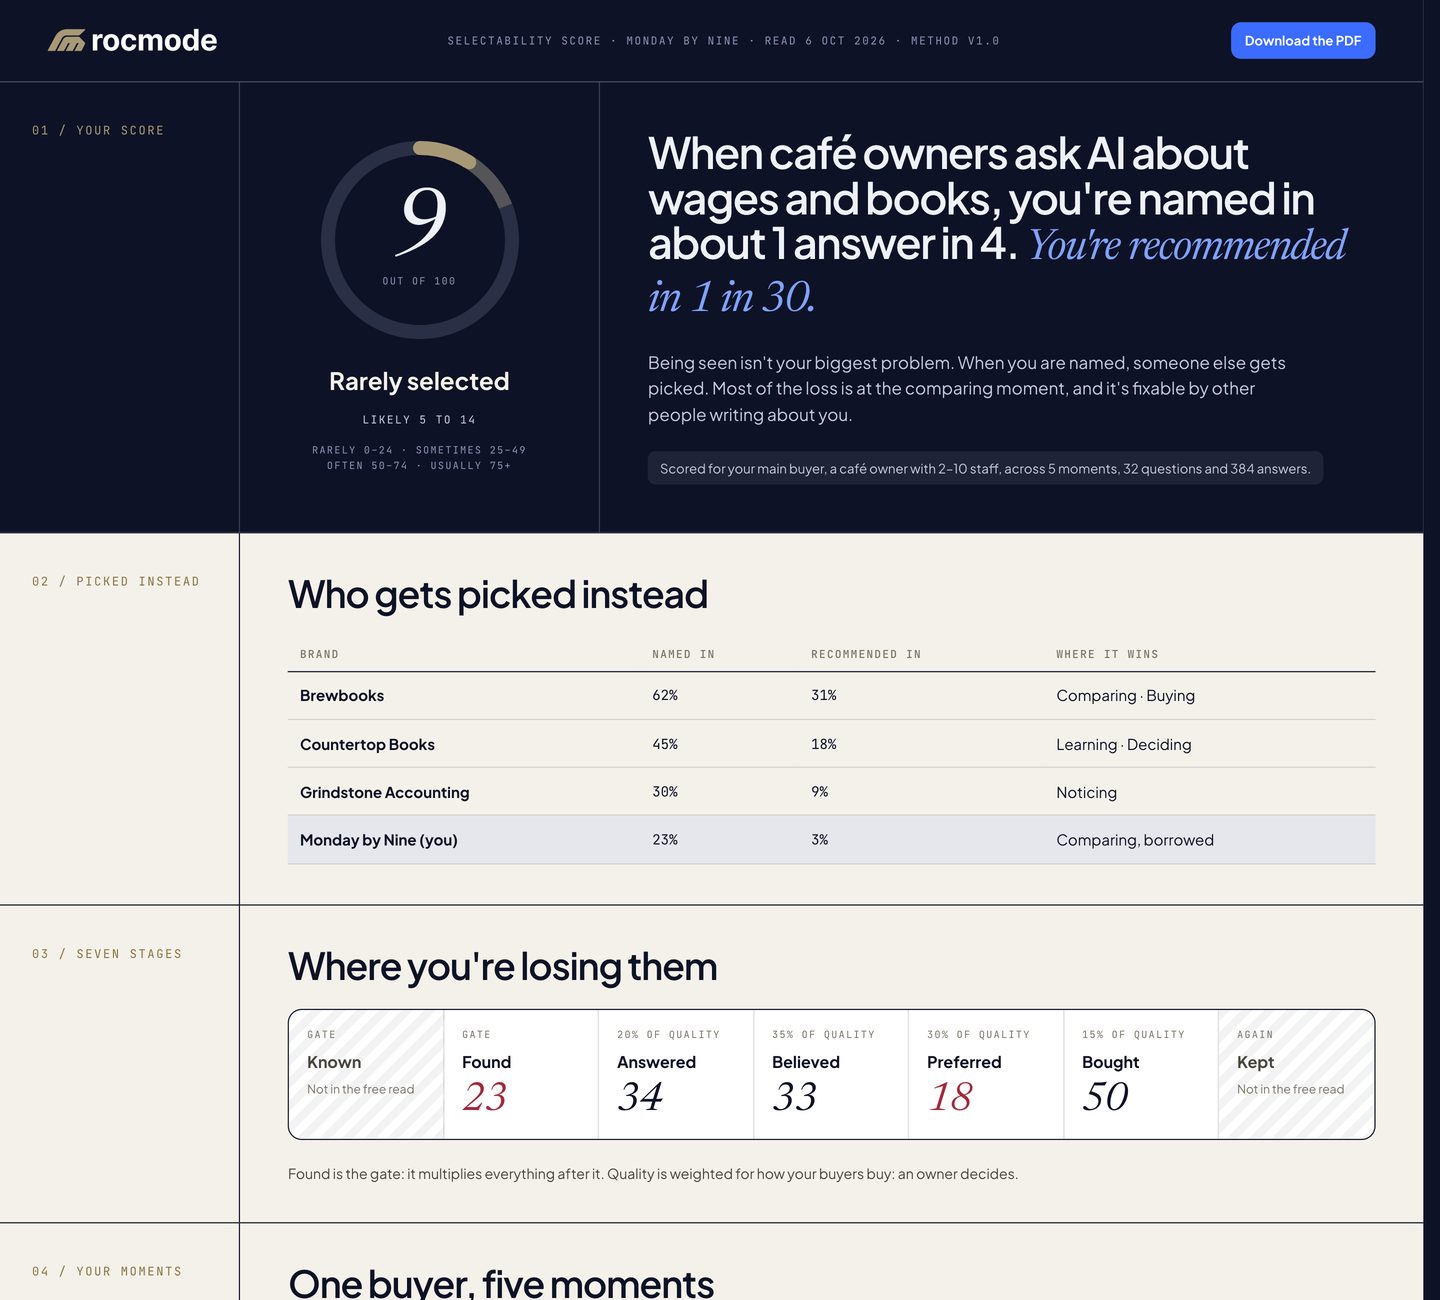
The score is out of 100, so the gap to 100 is what you're losing. Split that loss by stage and by moment, and the largest share is your biggest lever.
The list is the fixes, ranked by how much each should lift the score for the effort it takes. Every fix names its moment and its stage, and carries a predicted range.
Then comes the step most marketing skips. After a fix ships, ask again and record what moved. Predicted against measured is how the list earns trust.
Who owns the choice
Every team owns a number, and nobody owns the choice. The score gives the choice an owner.
This is my opinion, not a finding. One person should own the score and the list, across marketing and sales, with the standing to say no to work that moves no moment. In a small firm it's the owner. In a larger one it's often a commercial director or a head of growth. They don't own the channels; they decide which fix goes first, and which team does it. Believed belongs to everyone, which is why it needs an owner most. A contradiction can start in any team's page.
Beside your other numbers
The score doesn't replace the measures a finance director already trusts: attribution, mix modelling and experiments. eBay's paid-search test in Chapter 3 was an experiment, and that's the most trustworthy answer to "did this work?".
All three look backwards, at sales. The score looks forwards, at the choice. So use them together: the score says which fix to try, and an experiment proves whether it paid.
Where AI's influence shows up
Don't judge AI by the visits it sends. Most buyers who act on an AI answer arrive another way: they search your name, or type your address (Chapter 1). Their visits land in your reports as branded search and direct traffic.
So read three numbers together each quarter: the share of AI answers that name you at your moments, searches for your name, and direct visits. If your name starts appearing in answers and the other two rise a month or two later, that's AI at work. It isn't proof. A launch or a campaign moves the same numbers, so note what else changed. But it's a truer read than the AI line in your analytics.
What it changes
Budget follows the biggest lever. Money tends to drift toward whatever's easiest to count. One score gives it somewhere better to go.
NerdWallet, the American comparison site, made a version of this move in public. Search traffic to some of its pages was falling. Its chief executive, Tim Chen, told investors that marketing decisions would be "based on internal rate of return … rather than solely on in-quarter profitability" (NerdWallet).
And there's a measure that costs nothing. Ask every new customer how they found you, and include "an AI assistant" as an answer. Tally's onboarding survey found far more arrivals from AI than its analytics showed (Chapter 17).
What the score doesn't know yet
- The weights are judgement. They need calibrating against real sales, mode by mode.
- Nobody has yet shown that the score moves with share. Until that test is run, read it as an index of your odds, not a forecast of sales.
- Found and Preferred come from the same sample of answers, and those answers aren't fully independent. The real margin is wider than the arithmetic says.
- It can't see a sale. Only your own data can, and where you have it, it should outrank everything above.
Whose evidence this is. The method and the weights are mine, and RocMode, which I founded, sells software that runs them. Tally sells online forms, and its numbers are its own. NerdWallet's words come from its earnings call, as reported. eBay's test was run by eBay's own researchers. No peer-reviewed study has tested the score.
The loop
A score is only worth taking if it changes what you do next. The whole method is a loop, and it has six steps.
- Measure. Ask the same questions, of the same assistants, the same number of times. Score each moment.
- Diagnose. Find the stage where each moment is lost, and why. Usually something is missing: an answer you never published, a claim nobody else backs, a reason nobody can repeat.
- Write down the truth. Record what's true about you for that moment, once, in one place: the facts, the reason, the price, the limits (Chapter 10). Every channel draws from that record.
- Prove it. Put evidence beside every claim that needs it: a named customer, a figure with a source, an outside review (Chapter 16).
- Publish it. Put the answer and the proof where buyers and machines read: your site, the review platforms, the sources assistants cite (Chapters 15 and 22).
- Measure again. Use the same sample, unchanged. Record what you predicted beside what moved, and drop the fixes that did nothing.
Most teams run the first step and stop. Or they jump from the second to making more content. The work that moves the score is in steps three to five: fixing the source, not the symptom. A dashboard can tell you you're not believed. Only a truth you've written down, proved and published changes it.
In a quarter, it looks like this.
This afternoon, this quarter
take the five questions your buyers ask most. Put each to three AI assistants five times, without naming your brand. Count how often you're named, and how often you're the one recommended. That's a rough reading of Found and Preferred, for nothing.
start here. Score five moments by hand, using the worksheet in the appendix. Fix the biggest lever, then ask again.
Where RocMode comes in
I said at the start that I build software on this thinking. Here's why.
The seven stages are what being selected takes, and the loop is how you improve them. Most teams hold the pieces in seven places, or not at all. The facts sit in a brand book, the proof in a sales deck, the reviews on a platform nobody owns, and the AI answers go unread. So nobody can see that a moment was lost because one claim had no proof behind it.
That's why we built RocMode. It doesn't only measure selectability. It's built to run the whole loop in one place.
- It measures. It samples AI answers to your unbranded questions, scores each check in each moment, and runs the same sample again each period, so you see what moved.
- It diagnoses. It traces a lost moment to its cause: the question you haven't answered, the claim with no proof, the contradiction between two of your own pages, or the reason the machine gives instead of yours.
- It holds the truth. At its centre is BrandGraph, one governed record of what's true about your brand: each fact, claim and reason, the evidence behind it, and where it's published. A claim without a source is flagged before it goes out. When the price changes, it changes once.
- It shows its reasoning. Every item on the list carries its chain: which answers, which sources, which missing proof. You can check the working, not just the number.
- It closes the loop. Pages and content are drafted from that one record for you to approve, and the next sample shows whether the machine's choice changed.
There are two ways to start, and they suit different firms.
- Start here: do it yourself, for five moments. The appendix has the worksheet. An editable version, with every tool from the stage chapters, is free in the Selectability Playbooks at rocmode.com/playbooks. Five moments by hand take an afternoon to a day each quarter, and that's the right place to start.
- Use RocMode when you want fifteen or more, every quarter. At that size the asking, counting and fixing outgrow a spreadsheet.
Be clear about what it can't do. No software earns your reviews, wins you a reference customer or makes the pitch. It tells you which of those to do first, and proves whether they worked.
Today it scores five of the stages, Found through Bought, from AI answers and from your own site. Known and the renewal moments are in the method above and not yet in the product.
The formula is published, so you can check our working or do it yourself. Agencies and consultants can run the method for their clients too, and RocMode is built for agencies running it across many clients. The method belongs to whoever uses it.
Seen isn't selected. Now there's a way to tell the difference, and to close it.