Part five
Appendix: the self-score worksheet
This worksheet scores your Selectability by hand. It follows Chapter 30 step by step.
Be realistic about the time. A full sample is 45 answers per moment, so fifteen moments is 675 answers: several days by hand. For a first pass, use two assistants and three runs of each phrasing. That's 18 answers per moment, 270 for fifteen moments, and roughly a day. Five moments at the first-pass size take an afternoon.
The rubrics are my own working rules, drawn from the stage chapters. They're not tested against sales. A hand score is a rough reading, and its value is in repeating it the same way each quarter.
The ten steps
- Pick a mode. Choose the one from Chapter 7 that fits most of your sales. It sets the weights for the four quality checks.
| Mode | Answered | Believed | Preferred | Bought |
|---|---|---|---|---|
| Habitual | 10% | 20% | 15% | 55% |
| Quick choice | 15% | 25% | 15% | 45% |
| Considered personal | 25% | 30% | 30% | 15% |
| Owner-led business | 20% | 35% | 30% | 15% |
| Committee | 25% | 30% | 30% | 15% |
- List up to 15 moments. Each is one kind of buyer at one step, from your map in Chapter 12. Write each in the buyer's own words. Renew-or-switch moments count too, and are scored the same way.
- Write three unbranded questions per moment. Three different phrasings of what that buyer would ask. Make them long and specific, with the buyer's situation in them. None may name you.
- Run a presence sample. Put each phrasing to three assistants, five times each, in fresh sessions. That's 45 answers per moment. For a first pass, use two assistants and three runs: 18 answers. For each answer, note whether you were named, whether you were the one recommended, and the reason given. With 45 answers, the margin on Found is roughly 15 points either way; with 18, about 23. Both assume each answer is independent. Repeated phrasings to the same assistants aren't, so treat the real margin as wider.
- Rate the six checks from 0 to 100. Use the rubric table below, one moment at a time. If fewer than 10 answers in a moment name you, mark that moment's Preferred as unreliable. Score it, but don't rank a fix on it alone.
- Work out the gate and the quality. Gate = √(Known × Found). Quality = the weighted average of Answered, Believed, Preferred and Bought, using your mode's weights.
- Score the moment. Moment = Gate × Quality. If you work in points out of 100, divide the product by 100.
- Average the moments. A plain average is fine for a first score. Later, weight moments nearer the decision, and your main buyers, more heavily.
- Mark the band. 0 to 24 is rarely selected, 25 to 49 sometimes, 50 to 74 often, and 75 and over usually. Write the margin beside it.
- List the three biggest gaps. Look at the gate first, because a low gate multiplies everything else down. Then, for each quality check, multiply its weight by its shortfall from 100. The largest products, in the moments nearest the decision, are your list.
The rubrics
| Check | The tool | How to rate it from 0 to 100 |
|---|---|---|
| Known | The moment memory map (Ch 13) | Rate buyer memory and machine memory each: strong 100, weak 50, absent 0. Take the average. Buyer memory comes from ten customer interviews; machine memory from needs-based prompts and asking the machine about you by name |
| Found | The presence sample (Ch 14) | The share of your 45 unbranded answers that name you, as a percentage |
| Answered | The question chain map (Ch 15) | Score each link in the buyer's chain: answered in public 1, partly 0.5, avoided 0. Divide by the number of links, then multiply by 100 |
| Believed | The claim, proof and source inventory (Ch 16) | Score each claim about you: 0 if only you say it, 1 if one independent source backs it, 2 if two or more of different kinds do, 3 if assistants repeat it and cite them. Take 1 off for any live contradiction, but never go below 0. Average the scores, divide by 3, then multiply by 100 |
| Preferred | The reason gap sheet (Ch 17) | Average two shares. First: of the answers that name you, the share where you are the one recommended. Second: the reason-match rate. Ask recent buyers why they chose you, and score each answer 0 (no reason), 1 (a generic reason), 2 (your reason, roughly) or 3 (your reason, in words you would use). The rate is the share scoring 2 or 3 |
| Bought | The risk-removal ladder and decision friction audit (Ch 18) | Eight yes-or-no checks, 12.5 points each. The landing page repeats the reason, shows proof and gives a clear next step. There is a small first step, a way out, a plain recommendation, proof from someone like them, and someone to call. Where you have sales data for the moment, it outranks this |
| Kept | The promise ledger and renewal moment map (Ch 19) | Not a check of its own. Score your renew-or-switch moments with the six checks above. Your renewal and repeat data outranks the result |
The bookkeeper's worksheet
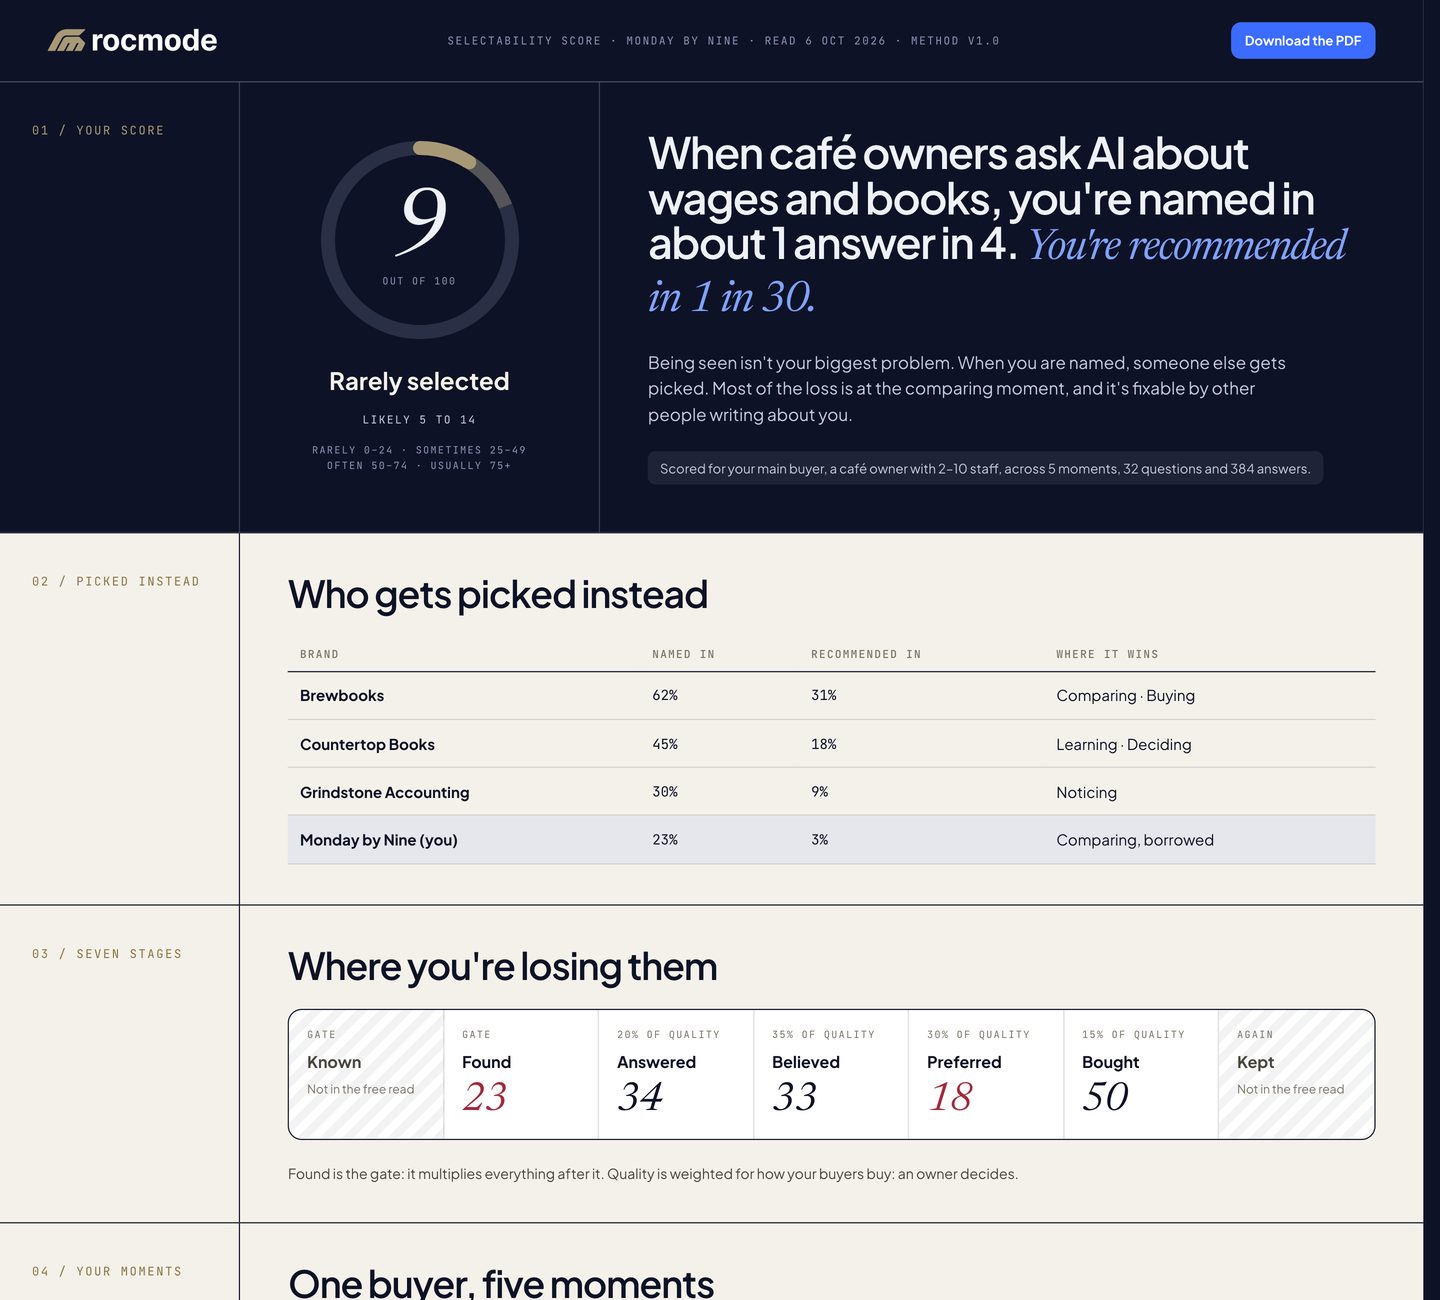
The bookkeeper for cafés is an invented example. Her offer is "Bookkeeping for cafés. Your wage cost against takings, every Monday by nine." All the figures below are invented to show the method. They describe her before the fixes in the stage chapters.
Her mode is owner-led business, so her weights are 20% Answered, 35% Believed, 30% Preferred and 15% Bought. She listed nine moments. Three are shown here.
| Moment, in the buyer's words | Known | Found | Answered | Believed | Preferred | Bought |
|---|---|---|---|---|---|---|
| A. "Wages ate the takings again this month" (comparing) | 75 | 40 | 38 | 33 | 35 | 50 |
| B. "Our accountant says the books are a mess before tax time" (learning) | 50 | 10 | 25 | 33 | 20 | 50 |
| C. "My accountant only sends numbers at year end" (buying) | 50 | 25 | 38 | 33 | 40 | 50 |
Moment A's Known is strong buyer memory and weak machine memory, from her moment memory map: (100 + 50) ÷ 2 = 75. Its Answered is two links answered, two partly and four avoided, from her question chain: (2 + 1) ÷ 8 = 38. Believed is 33 everywhere. Each of her claims is backed by exactly one independent source, a single client's review, and no assistant repeats it. That scores 1 out of 3 for every claim. Bought is four of the eight checks.
Moment A's Preferred shows how that check works. Of her 45 answers, 18 name her (Found 40). In 6 of those 18 she's the one recommended: 33.3%. She asked eight recent clients why they chose her, and three gave her reason, cafés and the Monday number, in words close to hers: 37.5%. The average of 33.3 and 37.5 is 35.
Moment B is different. Only about four or five answers name her there, fewer than 10, so she marks its Preferred as unreliable.
| Moment | Gate | Quality | Moment score |
|---|---|---|---|
| A | √(75 × 40) = 55 | 37 | 55 × 37 ÷ 100 = 20 |
| B | √(50 × 10) = 22 | 30 | 22 × 30 ÷ 100 = 7 |
| C | √(50 × 25) = 35 | 39 | 35 × 39 ÷ 100 = 14 |
| Average of the three | 14: rarely selected |
Fourteen sounds bleak, but it's useful. Found alone carries a margin of about 15 points, so she reads it as "rarely selected", not as 14 exactly.
Her three biggest gaps fall out of the arithmetic.
| Rank | Moment | Stage | What is wrong | The fix |
|---|---|---|---|---|
| 1 | B | Found (the gate) | The machine never names her at tax time | Write with the two accountants who refer her (Ch 13) |
| 2 | All | Believed | One client review backs her claims, and no assistant repeats them | Publish the twelve-month case, and ask two clients to mention the Monday number in reviews (Ch 16, Ch 17) |
| 3 | A and C | Preferred | When she is named, she is rarely the one recommended, and her reason is seldom given | Give reviewers and partners her reason in words they can repeat: "only cafés, the wage number every Monday" (Ch 17) |
The ranking follows step 10. Moment B's gate is the lowest, so it comes first. Then weight × shortfall: Believed is 0.35 × 67 = about 23 in every moment. Preferred is 0.30 × 65 = about 20 in A and 0.30 × 60 = 18 in C; B's is set aside as unreliable. Answered is only 0.20 × 62 = about 12 in A and C, so its fixes wait.
Rather than telling her to post more, the score told her that her weakest moment is held back by the gate, and every moment by belief. Both are fixed by other people writing about her, not by her writing more.
Next quarter she asks the same 27 questions, the same 15 times each. If moment B's Found has moved, the fix worked. If not, she tries the next one.
Blank templates
Template 1: Moments and questions.
| # | Buyer | Step | Moment, in the buyer's words | Phrasing 1 | Phrasing 2 | Phrasing 3 |
|---|---|---|---|---|---|---|
Template 2: Presence sample. One row per moment, per assistant. Five runs of each of the three phrasings gives 15 answers per row; three runs, for a first pass, gives 9.
| Moment | Assistant | Answers | Named | Recommended | Reason given | Who was named instead |
|---|---|---|---|---|---|---|
| 15 |
Template 3: Ratings and scores.
| Moment | Known | Found | Gate | Answered | Believed | Preferred | Bought | Quality | Moment score |
|---|---|---|---|---|---|---|---|---|---|
Template 4: The verdict.
| Date | Mode | Weights (A / Be / P / Bo) | Moments scored | Average score | Margin | Band | Method version |
|---|---|---|---|---|---|---|---|
Template 5: The three biggest gaps.
| Rank | Moment | Stage | What is wrong | The fix | Owner | Predicted lift | Measured lift |
|---|---|---|---|---|---|---|---|
Download the editable worksheet free at rocmode.com/playbooks, or have RocMode run it for you.