One Brand OS. One loop.
Measure your odds of being selected, fix the biggest gap, and measure again. Every product reads the same BrandGraph.
How RocMode works →Know where you stand
SelectabilityYour odds of being picked, moment by moment BrandYour BrandGraph and strategy, every fact sourcedProtect what’s true
BrandGuardEvery claim checked before it shipsDo the work
Website EngineYour site, rebuilt from the truth Email StudioBroadcasts and sequences, checked before they send Pitch EngineA credentials deck for each buyer, tracked Document StudioProposals and PDFs that stay in syncPlan and follow up
RFP EngineA brief agencies can answer, written from your record CampaignsA year of campaigns, judged on what you signed Journeys and SequencesFollow-up that never forgets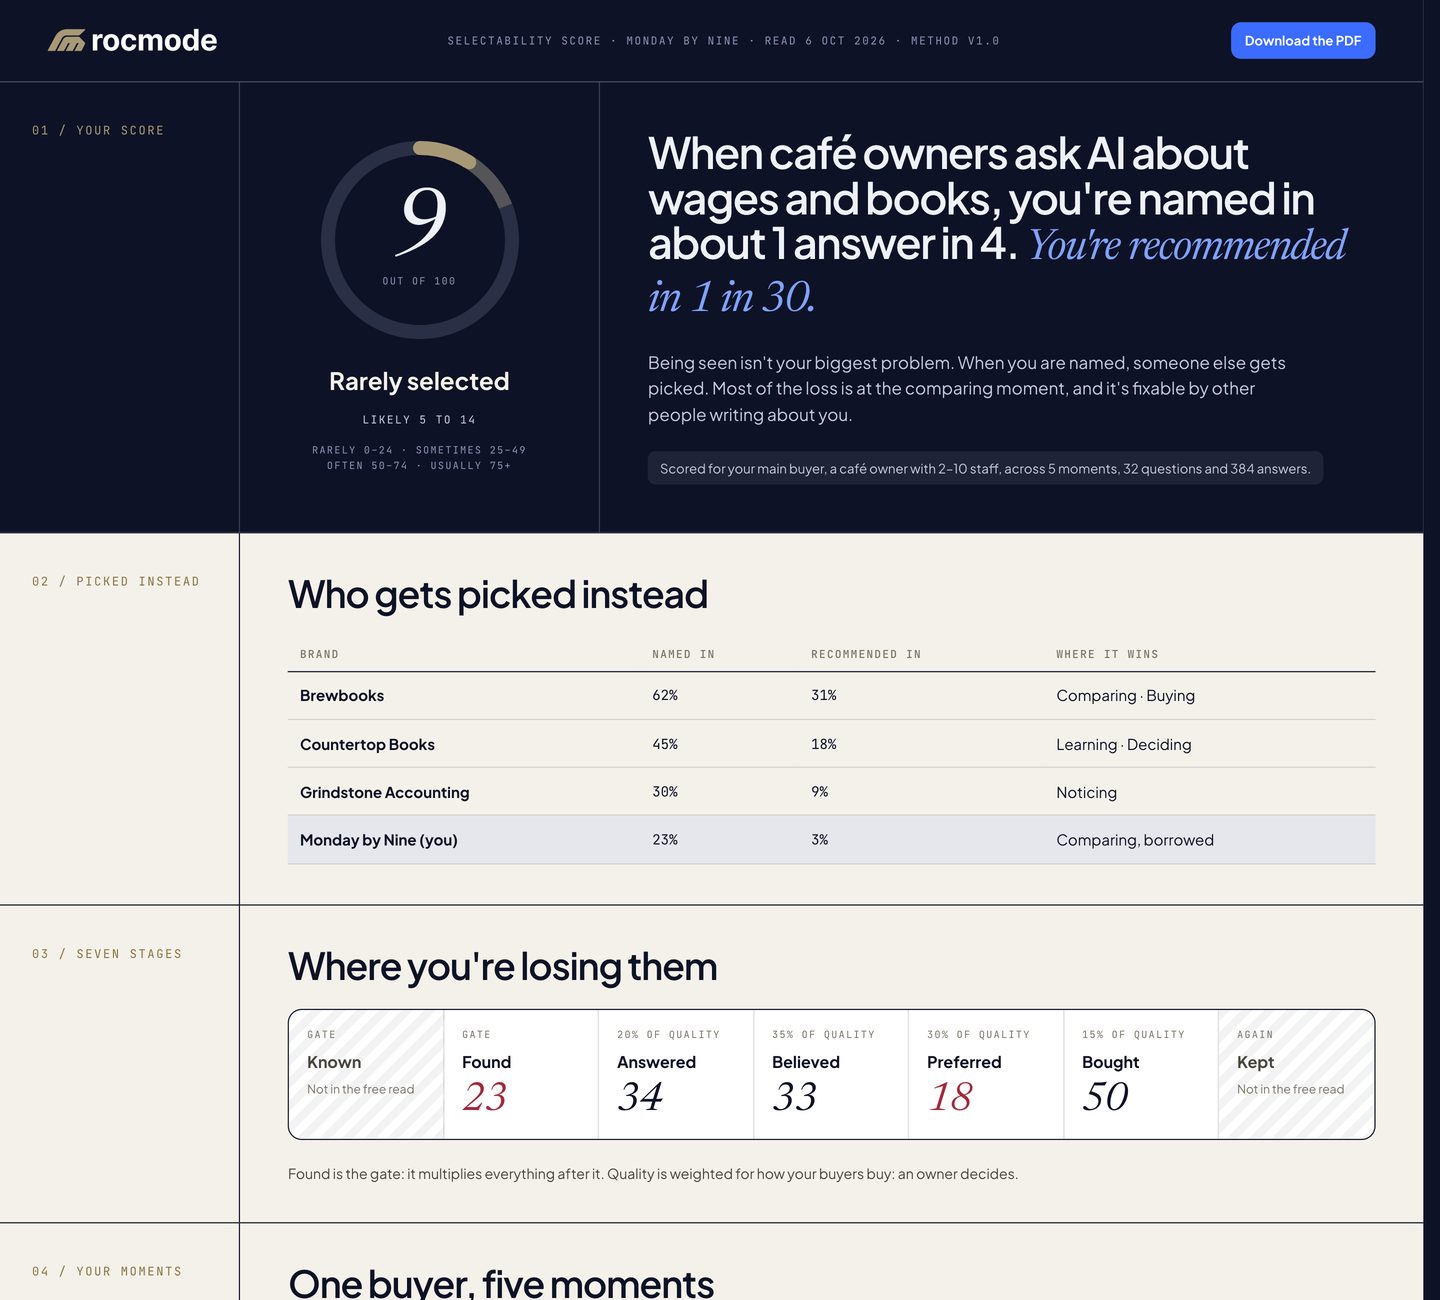
Get your Selectability Score
Who gets picked instead of you, and the three gaps to fix first. Free, no login.
Get your scoreSeen isn't selected.
Selectability is the odds that a buyer, at a given moment, picks you over the alternatives, doing nothing included.
What is Selectability? →The model
The seven stagesKnown to Kept. Being seen covers the first two Moments and buying modesOne kind of buyer, at one step, buying one way The loopMeasure, fix the biggest gap, ask again each quarterThe Score
How the Score worksv1.0The formula, the weights and the honesty rules, published Sample reportA full read for an invented brand, page by page GlossaryCompare, fairly
vs AI-visibility tools vs an agency vs doing it yourself vs doing nothingEach page says when the other option is the better choice.
Gate × quality, moment by moment, with a range. Questions that name you only test belief.
Read the method →One argument, three sizes.
The book tells you why, the playbooks tell you how, and your Score tells you where. All three are free.
The books
The manifestoFreeTwelve beliefs in ten minutes. Short enough to send your CEO Seen Isn't SelectedFreeMarketing's one job in the AI era. The whole book, free to read here The Selectability PlaybooksFreeEleven steps, fourteen builds, every templateResearch
Customer ZeroRocMode's own Score, published monthly, whether or not it improves Share your scoresHelp test the Score against real sales. Findings published, whatever they show Guides and findingsEvery finding with its source, and how strong it isEvery second Tuesday
The SelectionOne finding, one fix, one receipt
The whole book, free, right here.
All 206 pages, chapter by chapter. No email, no paywall.
Start readingWe make brands alive.
Brands are selected by buyers, and now by the machines that advise them. We hold ourselves to it first.
RocMode
AboutWhy we built it, and who built it Customer ZeroOur own numbers, published monthly TrustWhat we do with your brand's dataEvery buyer, every quarter.
The beta is limited to 30 brands. Free while it runs, and your price is held for 12 months after.
Request Beta access →Know where you stand
Selectability BrandProtect what’s true
BrandGuardDo the work
Website Engine Email Studio Pitch Engine Document StudioPlan and follow up
RFP Engine Campaigns Journeys and SequencesFor you
Marketing leaders Founders and CEOs Sales leaders Agencies and consultants Smaller businesses How RocMode works →Know your odds.
Your buyers’ questions, asked of five AI assistants, three times each, without your name in them. One score with its range, and the three gaps to fix first.
 Selectability ScoreMonday by Nine · read 7 Oct 2026 · method sel-score@0.1Download the PDF
Your buyer's questions, put to the machines.
“What reports should a café owner get from their bookkeeper?”
This answer named you.“Can a bookkeeper send me wage cost against takings every Monday?”
This answer recommended you.“Best bookkeeper for cafés in Brisbane that reports wages weekly”
This answer named others.Selectability ScoreMonday by Nine · read 7 Oct 2026 · method sel-score@0.1Download the PDFAI names you. It rarely picks you.
Likely 5 to 14. Named in about 1 answer in 4, recommended in 1 in 30.
Selectability ScoreMonday by Nine · read 7 Oct 2026 · method sel-score@0.1Download the PDFWho gets picked instead
Selectability ScoreMonday by Nine · read 7 Oct 2026 · method sel-score@0.1Download the PDFWhere you're losing them
Selectability ScoreMonday by Nine · read 7 Oct 2026 · method sel-score@0.1Download the PDFYour three biggest gaps. What to do is yours, free.
AI rarely names you when owners compare bookkeepers
Named in 50 of 120 comparing answers. Brewbooks was named in 89.
Your claims rest on one review, and no assistant repeats them
Of your 3 claims, 1 has one outside source and 2 have none.
When you’re named, Brewbooks is usually the one recommended
The reason AI gives for them: “specialises in hospitality”. Your reason, the Monday number, was given in 5 of 480 answers.
From your questions to your first fix.
Selectability ScoreMonday by Nine · read 7 Oct 2026 · method sel-score@0.1Download the PDFYour buyer's questions, put to the machines.
“Are hospitality-specialist bookkeepers worth paying more for?”
This answer named others.“What reports should a café owner get from their bookkeeper?”
This answer named you.“Can a bookkeeper send me wage cost against takings every Monday?”
This answer recommended you.“Best bookkeeper for cafés in Brisbane that reports wages weekly”
This answer named others.Example: Monday by Nine, the invented café bookkeeper from the book.
Selectability ScoreMonday by Nine · read 7 Oct 2026 · method sel-score@0.1Download the PDFAI names you. It rarely picks you.
Likely 5 to 14. Named in about 1 answer in 4, recommended in 1 in 30.
Example: Monday by Nine, the invented café bookkeeper from the book.
Selectability ScoreMonday by Nine · read 7 Oct 2026 · method sel-score@0.1Download the PDFWho gets picked instead
Example: Monday by Nine, the invented café bookkeeper from the book.
Selectability ScoreMonday by Nine · read 7 Oct 2026 · method sel-score@0.1Download the PDFWhere you're losing them
Example: Monday by Nine, the invented café bookkeeper from the book.
Selectability ScoreMonday by Nine · read 7 Oct 2026 · method sel-score@0.1Download the PDFYour three biggest gaps. What to do is yours, free.
AI rarely names you when owners compare bookkeepers
Named in 50 of 120 comparing answers. Brewbooks was named in 89.
Your claims rest on one review, and no assistant repeats them
Of your 3 claims, 1 has one outside source and 2 have none.
When you’re named, Brewbooks is usually the one recommended
The reason AI gives for them: “specialises in hospitality”. Your reason, the Monday number, was given in 5 of 480 answers.
Example: Monday by Nine, the invented café bookkeeper from the book.
Honest enough to act on.
Selectability ScoreMonday by Nine · read 7 Oct 2026 · method sel-score@0.1Download the PDFAI names you. It rarely picks you.
Likely 5 to 14. Named in about 1 answer in 4, recommended in 1 in 30.
Selectability ScoreMonday by Nine · read 7 Oct 2026 · method sel-score@0.1Download the PDFWho gets picked instead
Selectability ScoreMonday by Nine · read 7 Oct 2026 · method sel-score@0.1Download the PDFYour three biggest gaps. What to do is yours, free.
AI rarely names you when owners compare bookkeepers
Named in 50 of 120 comparing answers. Brewbooks was named in 89.
Your claims rest on one review, and no assistant repeats them
Of your 3 claims, 1 has one outside source and 2 have none.
When you’re named, Brewbooks is usually the one recommended
The reason AI gives for them: “specialises in hospitality”. Your reason, the Monday number, was given in 5 of 480 answers.
We scored ourselves first: 0 out of 100.
Named in none of the 30 questions our buyers ask. We publish our Selectability Score on the first Tuesday of every month, whether or not it improved.
You only need mention counts across assistants. A visibility tool does that well, for less. Come back when you want to know why you aren’t picked.
Is the score free?
Yes, for any brand: your main buyer, scored at their moments, with the three gaps to fix first. In the beta, every buyer is scored, every quarter.
Why five assistants, three times each?
Answers vary from one asking to the next. Asking more than once is what lets the score carry an honest range.
Can I see the formula?
Yes. The formula, the weights and the rules are published on The Method, and in chapter 30 of the book.
Every engine reads the same record.
So the site, the emails, the decks and the campaigns all say the same true thing. Get your score →